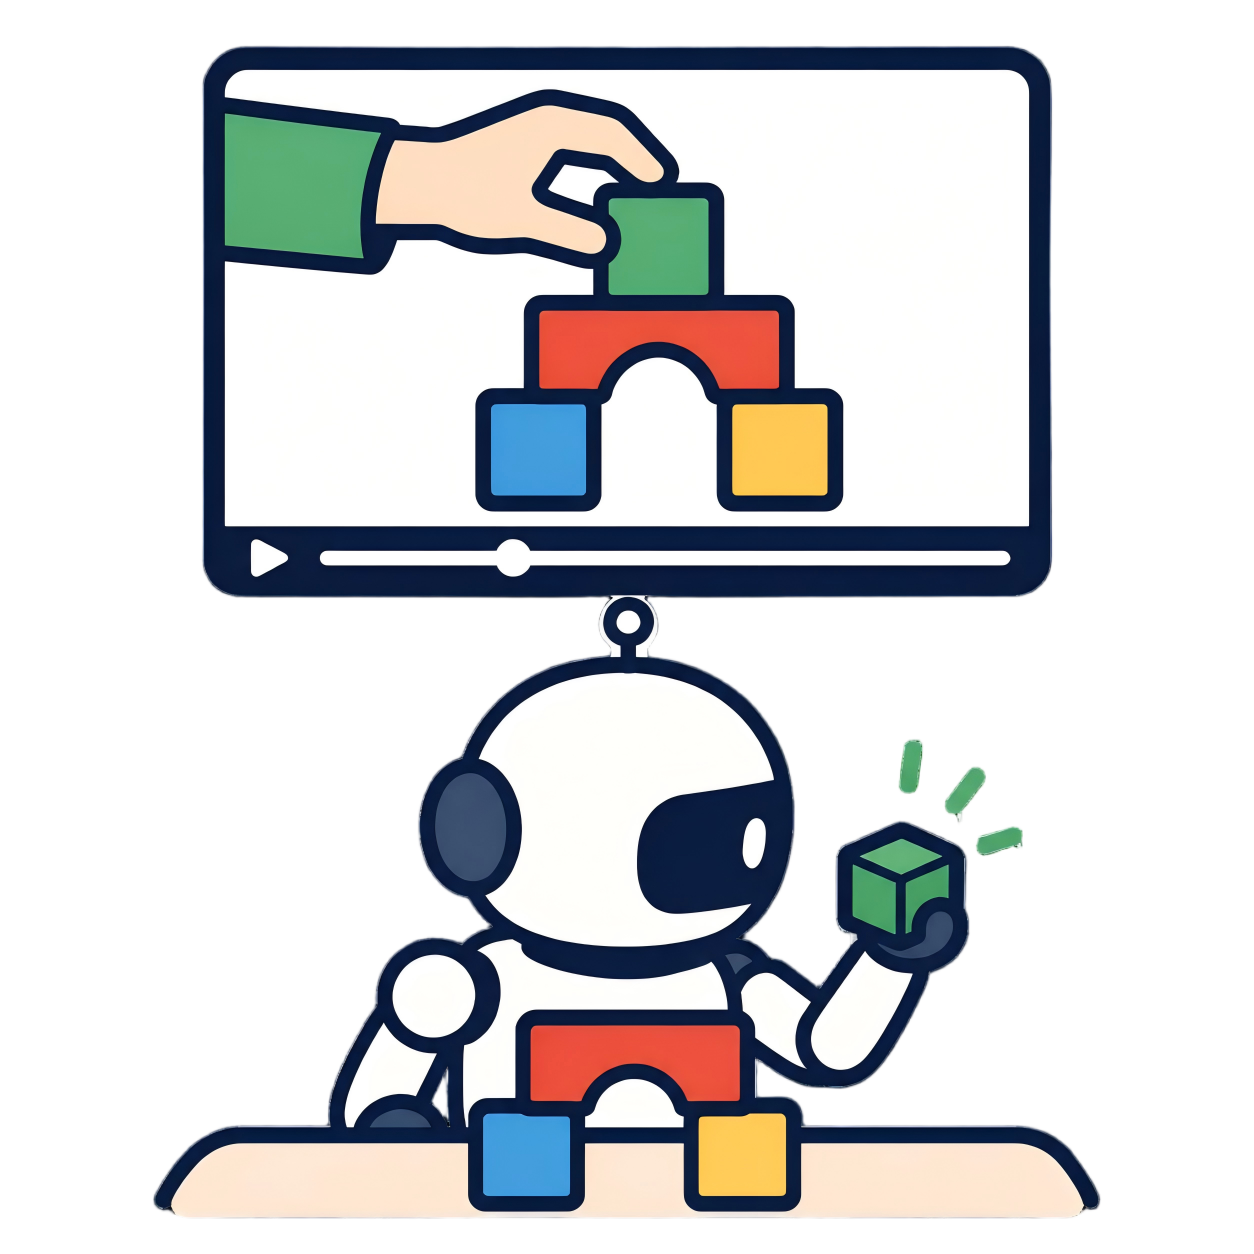
The four levels L0-L3
Each task is instantiated at four levels of progressive mismatch between the human demonstration and the robot's scene — from exact replay (L0) to functional substitution (L3).
Benchmark semantics
The level is a property of a demonstration-execution pair, not an input supplied to a policy. Goal predicates are used for simulator-side evaluation only. The table below summarizes what changes at each level and which fidelity the robot is expected to preserve.
| Level | Demonstration-to-execution change | Highest preserved fidelity | Simulation implementation |
|---|---|---|---|
| L0 | Same task-relevant objects and layout | Trajectory-level imitation | Base environment |
| L1 | Same objects, rearranged layout | Final object-state imitation | Base environment with spatial offsets |
| L2 | Same task semantics, different object instances | Semantic task completion | Base environment with instance substitution and task-specific mirroring |
| L3 | Different object semantics, reusable affordances | Underlying intent through affordance adaptation | Independent L3 environment |
Environment IDs
L0, L1, and L2 share one registered environment class; L3 has a separate registered class.
Names such as L2_TwoRobotStirSpoon-v1 are dataset and trajectory aliases, not
Gymnasium environment IDs.
| Level | Gymnasium environment ID |
|---|---|
| L0 | TwoRobotStirSpoon-v1 |
| L1 | TwoRobotStirSpoon-v1 |
| L2 | TwoRobotStirSpoon-v1 |
| L3 | TwoRobotStirSpoonL3-v1 |
The complete task mapping is stored in
examples/baselines/lerobot_dataset/task_mapping.json. Every task is a matched
set of four components: one base environment, one standalone L3 environment, one base and
one L3 motion-planning solution, and index in the dataset task mapping.
L2 left-right mirroring
L2 enables the task-specific object substitutions and the left-right scene mirror by default. The mirror is applied after episode initialization, so all task actors and articulations are transformed consistently. Robot root poses are mirrored by default as well.
Keep the scene mirror but preserve the original robot sides with:
configure_dual_task_level("L2", mirror_robot_pose=False)
The motion-planning runner exposes the same choice through
--no-mirror-robot-pose. When a mirrored episode is recorded,
RecordEpisode stores lr_mirror_applied in its metadata and
canonicalizes the paired wrist-camera/action ordering.
Evaluation
Evaluation and reward functions live in the environment. Dense rewards are built from
ordered phases (RewardTracker); these phase values are evaluation and training
signals and must not be provided as policy conditioning inputs in the
Imitator Game protocol. Use reward_mode="dense", "sparse" or
"none" as described in the quickstart.
Ready to modify your scenes? Enable domain randomization — randomize background textures and object placements — or collect data with the data collection guide.